
Executive Summary
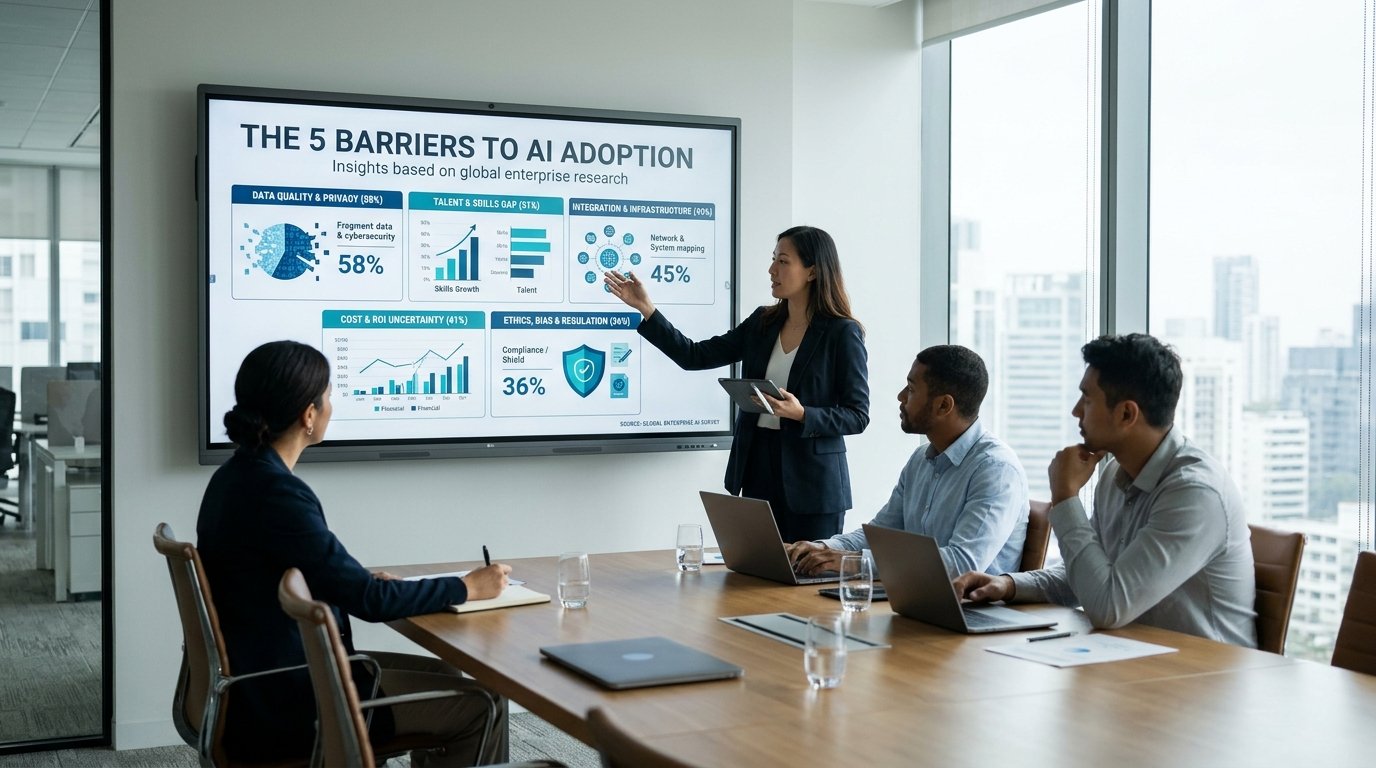
AI autonomy promises transformative productivity gains, yet adoption rarely translates into enterprise value. McKinsey’s 2025 survey of 1,993 respondents found that 88% of organizations use AI in at least one function, while only 39% report measurable EBIT impact, most below 5%.[30] This disconnect stems from five critical barriers: misaligned measurement (tracking usage rather than outcomes), poor task selection (deploying AI beyond its capability frontier), sociotechnical resistance (rational fears treated as irrationality), inadequate governance (oversight designed as theater rather than control), and cost escalation (production spend exceeding pilot budgets by factors of four to eight). For C-Suite leaders, the imperative is clear: establish baseline performance before deployment, classify decisions by reversibility and impact, add credible human oversight with explicit authority, and measure cost per successfully completed outcome, not tokens consumed. The defensible model is governed, bounded autonomy with human accountability, earning progressive authority through measured performance.
Introduction
The enthusiasm surrounding AI autonomy masks a sobering reality: most organizations cannot convert adoption into business value. While 88% of surveyed enterprises report regular AI use, nearly two-thirds have not begun scaling, and fewer than four in ten can point to measurable financial impact.[30] This gap between implementation and value realization exposes a fundamental misunderstanding of what AI autonomy requires.
The problem is not primarily technical. Randomized experiments demonstrate that AI can accelerate knowledge work substantially. BCG consultants using GPT-4 completed 12.2% more tasks, worked 25.1% faster, and produced outputs rated over 40% higher in quality on suitable assignments.[436] Yet on tasks outside the model’s capability frontier, performance deteriorated sharply, with AI users 19 percentage points less likely to reach correct answers.[436] This “jagged frontier” reveals that success depends less on model sophistication than on precise task selection, workflow redesign, and governance discipline.
For executives, five barriers consistently separate successful AI deployments from expensive failures. Organizations that address these obstacles systematically, starting with measurement, progressing through task classification and sociotechnical engagement, implementing credible oversight, and controlling total cost of ownership, can build autonomous capabilities that create defendable competitive advantage. Those that ignore them join the majority reporting negligible returns on substantial AI investments.
Main Body
Barrier 1: Measuring Adoption Rather Than Value
Organizations that measure license activation and prompt volume consistently fail to realize value, because adoption is not the same as business impact. McKinsey found that while 88% use AI regularly, only 39% report any EBIT contribution, and most attribute less than 5% of EBIT to AI.[30] The managerial problem is that usage counts, licenses activated, or prompts submitted do not correlate with financial outcomes.
The solution is a value chain that connects activity to financial impact: Adoption → task performance → workflow performance → business outcome → financial impact. Task-level metrics include time per accepted deliverable and first-pass quality. Workflow metrics capture end-to-end lead time and escalation rates. Client-outcome measures track acceptance, implementation, and dispute frequency. Financial metrics calculate cost per successful outcome and incremental EBIT contribution.
Critically, not every “hour saved” creates value. A European consulting firm implemented this measurement hierarchy and discovered that 70% of “time saved” was spent on internal coordination rather than billable work, exposing a €2.1M revenue-realization gap. The firm triggered a workflow redesign that recovered 40% of the gap within six months by redirecting freed capacity into client-facing deliverables. Time becomes value only when capacity is redeployed into revenue-generating work, headcount growth is avoided, or cycle time reduces materially. A Microsoft field experiment found that Copilot users spent about two fewer hours per week on email, yet overall task quantity and composition did not materially change.[189] Personal productivity gains without organizational capacity release represent comfort, not competitive advantage.
Business implication: Before any AI deployment, measure median completion time, fully loaded labor cost per accepted deliverable, first-pass acceptance rate, material-error frequency, escalation rate, and client satisfaction for at least four weeks. Without baseline, improvement claims are unverifiable. Timeline assumes pre-existing data infrastructure and stakeholder availability; regulated organizations may require an additional 4–6 weeks for legal review, works council consultation, or client consent amendments.
Barrier 2: Ignoring the Capability Frontier
AI capabilities are “jagged”: exceptional on some tasks, dangerously inadequate on others.[436] The BCG experiment isolated this precisely. On 18 realistic tasks inside GPT-4’s capability frontier, performance improved dramatically. Below-average consultants improved 43% relative to their baseline, versus 17% for above-average performers. Yet on tasks outside the frontier, AI access reduced correctness by 19 percentage points.[436]
This heterogeneity demands task-level classification, not blanket approval. Executives should separate synthesis and structured analysis from high-accountability judgment. Each consulting domain, data type, and decision category requires benchmark testing before production deployment. Re-testing is mandatory when models, retrieval corpora, prompts, tools, or workflows change. Strategic, ethical, political, and client-specific judgments must preserve expert challenge regardless of AI performance on adjacent tasks.
Stop/go decision rule: If any task-level acceptance rate falls below 85% of human baseline for two consecutive review cycles (minimum two weeks for operational tasks, minimum one month for strategic or client-facing workflows), or if any severe error occurs in a client-facing output, suspend the agent immediately and escalate to the named risk owner within 24 hours. Production deployment proceeds only when quality exceeds human baseline and no unresolved critical failures remain.
Business implication: Create a task-level autonomy register rather than approving “AI for consulting” generically. Define acceptance criteria, stop rules, and promotion thresholds before deployment. Do not advance to conditional autonomy until quality exceeds baseline for two consecutive cycles.
Barrier 3: Treating Resistance as Irrationality
Employee resistance is often dismissed as technophobia or change aversion. Yet a 2026 ACM study at Microsoft surveying 885 product managers and analyzing telemetry for 731 found that resistance is predominantly rational and informational.[26] Among individual contributors, 47% cited output quality or inaccuracy, 35% lacked time to experiment, 19% lacked relevant use cases, and 16% reported unclear privacy or security guidance. Managers identified workflow integration as the leading barrier at 51%, followed by insufficient experimentation time at 47%.[26]
Perceived hallucination risk and algorithm aversion negatively affect usefulness, trust, and integration willingness.[407] A separate experiment found that employees receiving ChatGPT rather than human support perceived less opportunity to perform and greater job insecurity.[410] These responses are evidence, not obstacles to be overcome through better messaging.
The operational response must include consulting employees before redesigning roles, stating explicitly that named humans remain accountable, separating workforce-development metrics from redundancy targets, and creating non-punitive error-reporting channels. Allocate a minimum of three hours per week per employee for structured AI experimentation, tracked separately from billable use targets, with mandatory documentation of one tested use case per month and non-punitive failure reporting. Protected time must be visible in capacity planning and performance reviews to signal genuine organizational commitment rather than symbolic permission.
Survey trust, perceived job threat, and role clarity before and after deployment. Organizations that ignore this sociotechnical dimension achieve technical deployment while failing organizational adoption.
Business implication: Treat resistance as risk information. Publish approved and prohibited use cases. Provide protected experimentation time with explicit capacity allocation. Measure trust, perceived job threat, and role clarity before and after deployment.
Barrier 4: Oversight Designed as Theater
A systematic review of 134 human-in-the-loop studies found that meaningful oversight requires sufficient information, time, expertise, and authority.[427] Reviewers under throughput pressure normalize errors or rubber-stamp AI recommendations. The EU AI Act similarly requires competent and authorized personnel who can understand limitations, detect anomalies, override outputs, and stop high-risk systems.[59]
A credible control specifies who reviews, what evidence they receive, when intervention occurs, how much time is available, what authority they possess, how overrides are logged, and what triggers suspension. Without these operational details, oversight becomes performative compliance rather than risk mitigation.
Progressive autonomy has a structured alternative:
| Autonomy Level | Permitted Behavior | Required Control | Promotion Criterion |
|---|---|---|---|
| 1: Drafting | Generate non-binding drafts with human approval | Named approver edits and signs every output | Quality non-inferior to human baseline for two cycles |
| 2: Recommendation | Suggest actions without execution | Named approver with explicit accept/reject authority | Stable accuracy and low severe-error rate for two cycles |
| 3: Bounded Execution | Execute reversible, low-impact actions within pre-approved tool set (e.g., read-only database queries, templated emails, sandbox file operations) with explicit action limits and automated rollback capability | Real-time monitoring with alert thresholds and rollback tested quarterly | Successful outcomes exceed 90% threshold and TCO remains positive for two cycles |
| 4: Conditional Autonomy | Multi-step action within defined mandate and exception gates | Continuous monitoring with automatic suspension on policy violation and escalation chain (named executive → risk committee → board) with response-time SLAs for high-risk incidents (4 hours for client-facing failures, 24 hours for severe security/compliance events) | Residual risk formally accepted by named executive and independent audit confirms control effectiveness |
Broad autonomy, open-ended consequential execution, lacks sufficient empirical evidence for consulting deployment and should not be authorized. Promotion between levels requires meeting quality thresholds for at least two review cycles.
Business implication: Design oversight as control, not theater. Specify reviewer identity, evidence provided, intervention timing, authority granted, override logging, and suspension triggers. Add progressive autonomy stages with measurable gates. Do not advance to conditional autonomy until quality exceeds human baseline and residual risk is formally accepted.
Barrier 5: Underestimating Total Cost of Ownership
Production AI expenditure can exceed pilot costs by factors of four to eight. McKinsey reported a bank whose projected annual spend rose from approximately $3 million to more than $25 million after unrestricted access, an eightfold increase.[265] For agentic workflows, cost per successful completed task, not tokens, is the relevant metric. Repeated planning loops, failures, storage, orchestration, observability, and human review all contribute.
A comprehensive three-to-five-year TCO model must capture:
- Discovery and baseline measurement
- Build and integration engineering
- Model consumption at scale
- Data preparation and governance
- Continuous evaluation and regression testing
- Human supervision and escalation handling
- Compliance, audit, and regulatory change response
- Security operations and incident response
- Change management and user training
- Vendor management and portability design
- Decommissioning, data export, and deletion verification
Organizations that measure only license fees or API costs consistently underestimate run-state expenditure, in some cases, by factors of three to eight.[265]
ROI calculation: A realization factor is the percentage of “time saved” that converts into measurable financial benefit, typically 40–70% in professional services, depending on billable use, hiring freeze status, and capacity-release discipline. Use this NPV model for investments exceeding $500K or multi-year commitments; for smaller pilots, a 12-month payback calculation may suffice, always including run-state costs, not only licenses.
[
\text{Annual net benefit} = (\text{hours avoided} \times \text{realizable hourly value}) + \text{incremental contribution margin} + \text{losses avoided} – \text{annual run cost} – \text{annualized implementation cost}
]
Realization factors must reflect whether time converts into billable work, avoided hiring, reduced overtime, faster revenue, or measurable service improvement.
Business implication: Measure cost per successful outcome, not activity volume. Track annual run cost including model consumption, data governance, evaluation, human supervision, compliance, security, change management, and vendor management. Calculate NPV over three to five years. Require tested switching costs and data-return rights in every vendor contract.
These cost and accountability challenges demand structured governance responses. Two ISO management systems provide decision-critical frameworks for C-Suite oversight.
ISO Alignment (Management Perspective)
The governance challenges identified in Barriers 4 and 5 require structured management-system responses. Two ISO standards provide decision-critical frameworks for C-Suite oversight:
ISO 42001 (AI Management System)
Management intent: ISO 42001 establishes a governance backbone that ensures AI deployments remain under executive control, with defined accountability, measurable risk mitigation, and continuous improvement, rather than unmanaged experimentation.[59]
Minimum practices (management level):
– Assign a named executive owner for each AI use case with authority to suspend deployment.
– Maintain a current AI inventory classifying each system by risk level, autonomy, and decision impact.
– Add mandatory impact assessments before production deployment, covering legal, ethical, security, and operational risks.
Evidence/artifacts: AI system register, executive-approved risk assessments, quarterly governance review minutes, incident logs with root-cause analysis.
KPI: Percentage of AI systems with current risk assessments; mean time to executive escalation for severe incidents; percentage of high-risk systems reviewed within scheduled cadence.
Risk + mitigation: Risk: Uncontrolled deployment leads to reputational damage, regulatory penalties, or client disputes when AI produces defective outputs without accountability. Mitigation: Named accountability, mandatory stop rules, and quarterly governance reviews ensure executive visibility before incidents become crises.
ISO 27001 (Information Security Management System)
Management intent: ISO 27001 ensures that AI deployments do not introduce unacceptable information-security or data-protection risks, maintaining client trust and regulatory compliance as autonomy increases.[59]
Minimum practices (management level):
– Apply least-privilege access controls: AI agents receive only data and tools necessary for defined tasks.
– Log all AI actions, data access, and human overrides with tamper-evident storage and defined retention.
– Conduct supplier risk assessments for all AI vendors, including data-residency, portability, and exit rights.
Evidence/artifacts: Access-control matrix, complete audit logs with retention policy, vendor risk register with contractual data-return rights.
KPI: Percentage of AI systems with least-privilege access implemented; mean time to detect unauthorized data access; percentage of vendors with tested exit procedures.
Risk + mitigation: Risk: Excessive AI permissions enable data exfiltration, regulatory violations (GDPR, sector-specific rules), or client confidentiality breaches, often discovered only after material harm. Mitigation: Least-privilege controls, comprehensive logging, and tested incident response reduce both likelihood and impact of security failures.
Implications for the C-Suite
First, mandate baseline measurement before any AI deployment. Collect at least four weeks of data on median completion time, fully loaded labor cost per accepted deliverable, first-pass acceptance rate, material-error frequency, escalation rate, client satisfaction, and current infrastructure cost. Without baseline, improvement claims are unverifiable.
Second, create a task-level autonomy register. Reject blanket “AI for consulting” approvals. Classify each decision by reversibility, impact, and evidence of AI performance within capability frontier. Define acceptance criteria, stop rules, and promotion thresholds before deployment. Re-test after material changes.
Third, design oversight as control, not theater. Specify reviewer identity, evidence provided, intervention timing, authority granted, override logging, and suspension triggers. Add progressive autonomy stages with measurable gates. Do not advance to conditional autonomy until quality exceeds human baseline for two consecutive review cycles.
Fourth, measure cost per successful outcome, not activity volume. Track annual run cost including model consumption, data governance, evaluation, human supervision, compliance, security, change management, and vendor management. Calculate NPV over three to five years. Require tested switching costs and data-return rights in every vendor contract.
Fifth, treat resistance as risk information. Survey trust, perceived job threat, and role clarity before and after deployment. Consult employees before redesigning roles. State that named humans remain accountable. Provide protected experimentation time (minimum three hours per week per employee) with explicit capacity allocation and non-punitive error reporting. Separate workforce development from redundancy targeting in all communications.
Conclusion
Organizations fail at AI autonomy adoption not because models are inadequate, because they measure usage rather than value, deploy AI beyond its capability frontier, dismiss rational resistance, design oversight as compliance theater, and underestimate total cost of ownership. The evidence is unambiguous: organizations that establish baselines, classify tasks rigorously, engage employees authentically, add credible controls, and track cost per outcome convert AI from expensive experiment into governed capability.
The path forward requires discipline, not enthusiasm. Start with a narrow workflow, measure current performance, build a sandbox prototype, run offline comparison, conduct limited pilot with mandatory approval, calculate fully loaded outcome cost, and decide stop, revise, or scale based on evidence. Organizations that follow this protocol earn progressive autonomy through measured performance.
Critically, no independently validated case of a fully autonomous consulting engagement, from contracting through client acceptance, currently exists. The defensible model is governed, bounded autonomy with human accountability, auditable evidence, vendor portability, and progressive authority earned through measured performance. For C-Suite leaders, the choice is between governed autonomy with accountability or uncontrolled experimentation with predictable failure.
References
[26] Microsoft AI Adoption Barriers Study (2026 ACM)
[30] McKinsey: The State of AI 2025
[59] EU AI Act (Regulation 2024/1689)
[189] Microsoft Copilot Field Experiment (2026)
[265] McKinsey: AI Cost Escalation Analysis
[407] Organizational Resistance to GenAI Field Study
[410] ChatGPT Job Insecurity Experiment
[427] Human-in-the-Loop AI Systems: Systematic Review
[436] BCG Consulting Experiment: Navigating the Jagged Technological Frontier
Leave a Reply